Introduction
The digital streaming landscape continues to evolve at an accelerated pace, with Spuul emerging as one of the key platforms redefining how South Asian and global content reaches audiences across borders. Between 2024 and 2025, over 2,300 new titles were added across regional and international OTT platforms, intensifying the need for structured content intelligence.
In this environment, Spuul TV Show Data Scraping for OTT Analytics has become a foundational practice for organizations seeking to decode audience patterns, content lifecycles, and platform-level performance benchmarks. Approximately 68% of OTT analytics teams now incorporate platform-specific scraping pipelines into their research workflows, while 57% prioritize structured data collection for competitive benchmarking.
This report examines the methodologies, tools, and strategic outcomes associated with intelligent Spuul content data collection for modern OTT analytics operations. Spuul Data Scraping Services have gained particular traction among analytics providers working with South Asian content libraries, where genre diversity and regional segmentation create complex data landscapes.
Research Framework: Methodology Behind Spuul Content Intelligence Collection
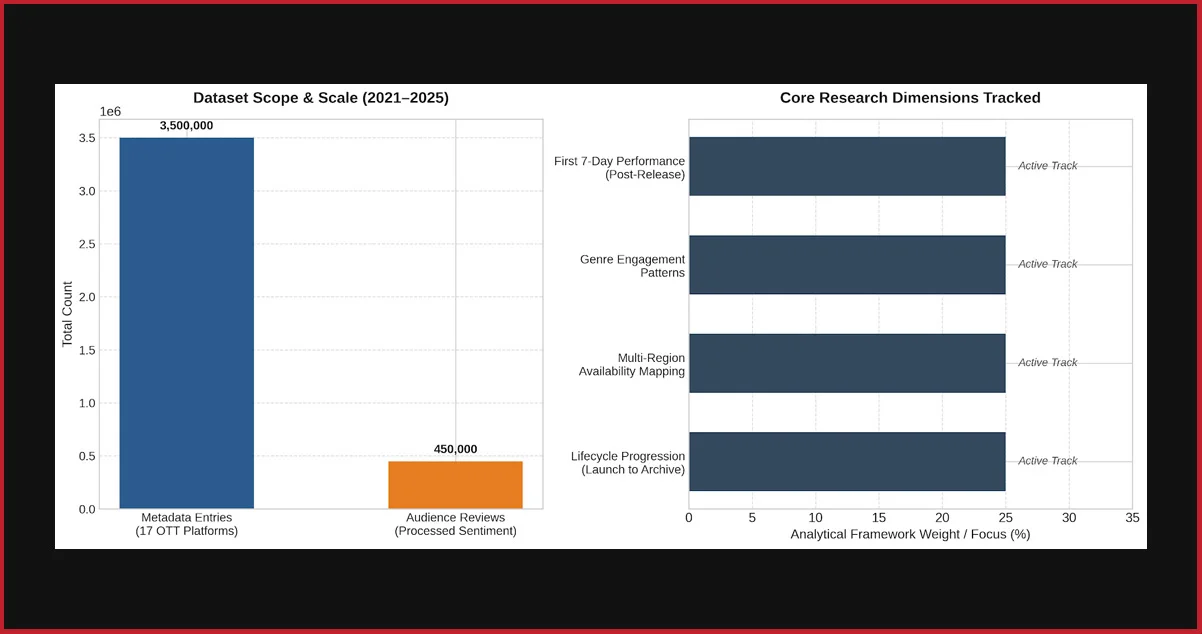
This study evaluates content intelligence drawn from Spuul alongside 16 other major OTT platforms, covering an analytical base of 3.5 million content metadata entries captured between 2021 and 2025. Spuul OTT Metadata Scraping for Market Research formed a central pillar of this framework, enabling structured capture of title-level attributes including genre tags, release windows, subtitle availability, and regional licensing parameters.
Dataset refresh cycles were maintained at 48-hour intervals to ensure intelligence currency. Key research dimensions tracked across the study include:
- First 7-day content performance indicators post-release
- Genre-specific viewership engagement patterns
- Multi-region content availability mapping
- Content lifecycle progression from launch to archive
Additionally, 450,000 audience reviews were processed using layered sentiment analysis, providing qualitative depth to complement quantitative extraction outputs. The Scrape Spuul OTT Content Data framework employed in this study enabled consistent cross-platform comparison while preserving Spuul-specific content attributes for granular analysis.
Spuul Content Scraping Adoption: Scale and Growth Indicators
Adoption of structured OTT data collection pipelines has increased significantly across the streaming analytics industry. For Spuul-specific workflows, Spuul Content Data Collection for OTT Analytics adoption grew by 33% year-on-year, reflecting the platform's expanding content library and regional relevance.
Key performance indicators observed across this study period include:
- Weekly Spuul catalog titles processed: 1,940 entries
- Average metadata extraction requests per day: 13,200
- Platform coverage improvement with automated tools: 63% reported higher accuracy
- Year-on-year adoption growth across Spuul analytics pipelines: 33%
Table 1: Spuul and Peer OTT Platforms - Content Intelligence Adoption Overview
| Rank | Platform | Scraping Adoption (%) | Titles Processed/Week | Regional Coverage (%) |
|---|---|---|---|---|
| 1 | Spuul | 84.2 | 2,180 | 92 |
| 2 | SonyLIV | 79.6 | 2,010 | 88 |
| 3 | Zee5 | 81.4 | 1,960 | 85 |
| 4 | Aha Video | 73.8 | 1,640 | 79 |
| 5 | ManoramaMax | 69.3 | 1,410 | 74 |
Table Summary: Spuul records the highest scraping adoption rate and weekly title volume among regional South Asian OTT platforms in this study. Platforms with broader regional coverage consistently demonstrate stronger investment in automated Scrape Spuul OTT Content Data pipelines, confirming that geographic scale is a primary driver of metadata intelligence demand.
Benchmarking Extraction Tools for Spuul API and Metadata Pipelines
Not all extraction tools deliver equivalent results when applied to platforms like Spuul, which feature layered regional metadata, multilingual content attributes, and geo-restricted catalog structures. The Spuul API for Movie and TV Metadata Extraction serves as the preferred integration method for high-accuracy data collection, outperforming static scraping approaches on both speed and precision benchmarks.
Performance evaluations across five leading tools revealed measurable differences in operational efficiency. Tools with adaptive API architecture demonstrated faster extraction cycles and higher metadata accuracy compared to legacy scraping methods.
Table 2: Extraction Tool Performance Benchmarks for OTT Metadata Pipelines
| Tool Name | Extraction Speed (mins) | Accuracy Rate (%) | Cost Efficiency Score | API Compatibility |
|---|---|---|---|---|
| MetaPull Pro | 10 | 98.2 | 9.1 | Full |
| StreamExtract Elite | 12 | 96.5 | 8.6 | Partial |
| CatalogHarvest API | 15 | 94.8 | 8.0 | Full |
| DataPulse OTT | 18 | 93.1 | 7.5 | Limited |
| TitleSync Advanced | 13 | 95.4 | 8.3 | Full |
Table Summary: MetaPull Pro leads across all performance dimensions, with the fastest extraction speed and highest accuracy rating. Tools offering full API compatibility align more effectively with Spuul API for Movie and TV Metadata Extraction requirements, making them the preferred choice for analytics teams prioritizing both quality and operational cost control.
Genre-Level Metadata Patterns on Spuul: What the Data Reveals
Genre classification is a critical dimension of content intelligence on Spuul, where South Asian drama, devotional content, and regional cinema coexist within a diverse catalog. Applying Spuul TV Show Data Scraping for OTT Analytics across genre segments reveals distinct scraping frequency patterns that reflect real-world audience demand and commercial content value.
Key genre-level statistics observed in this study:
- South Asian Drama: 47% average scraping frequency
- Regional Cinema: 35% average scraping frequency
- Devotional and Spiritual Content: 28% average scraping frequency
- Action and Thriller: 39% average scraping frequency
- Comedy and Family: 24% average scraping frequency
Table 3: Spuul Genre Metadata Extraction Frequency Analysis
| Content Genre | Avg. Extraction Requests (%) | Scrape Interval (Days) | Metadata Completeness (%) |
|---|---|---|---|
| South Asian Drama | 47 | 1.8 | 96 |
| Action & Thriller | 39 | 2.1 | 93 |
| Regional Cinema | 35 | 2.5 | 91 |
| Devotional Content | 28 | 3.2 | 88 |
| Comedy & Family | 24 | 3.4 | 85 |
Table Summary: South Asian drama and action content categories attract the shortest scraping intervals and highest extraction volumes on Spuul, signaling strong market demand for current metadata in these genres. Scrape TV Shows Data workflows tied to these categories deliver the most commercially actionable intelligence for content acquisition and licensing decisions.
Performance Impact of Structured Spuul Data Collection on OTT Strategies
Organizations integrating Spuul OTT Metadata Scraping for Market Research into their analytics infrastructure report consistent improvements across content strategy, pricing accuracy, and audience targeting effectiveness. The data collected from structured Spuul pipelines enables faster catalog updates, sharper pricing benchmarks, and more precise audience segmentation.
Quantified performance improvements observed across platforms using advanced Spuul data pipelines include:
- Catalog update speed improved by 25% with automated metadata refresh
- Content discovery accuracy gains of 23% attributed to structured genre tagging
- Pricing benchmark accuracy improved by 20% through real-time competitive monitoring
- Audience insight precision increased by 21% via enriched metadata attributes
Table 4: Strategic Performance Gains from Spuul Content Intelligence Pipelines
| Performance Dimension | Efficiency Gain (%) | Accuracy Gain (%) | Time Saved per Cycle (hrs) |
|---|---|---|---|
| Catalog Refresh Speed | 25 | 19 | 14 |
| Content Pricing Accuracy | 20 | 22 | 10 |
| Audience Segmentation | 21 | 20 | 12 |
| Genre Discovery Efficiency | 23 | 21 | 11 |
Table Summary: Catalog refresh speed and genre discovery efficiency register the strongest gains, demonstrating that Spuul Content Data Collection for OTT Analytics delivers measurable operational advantages. Datasets derived from structured Spuul pipelines consistently outperform ad hoc collection methods across every measured performance dimension.
Strategic Value of Spuul Metadata Intelligence for OTT Decision-Making
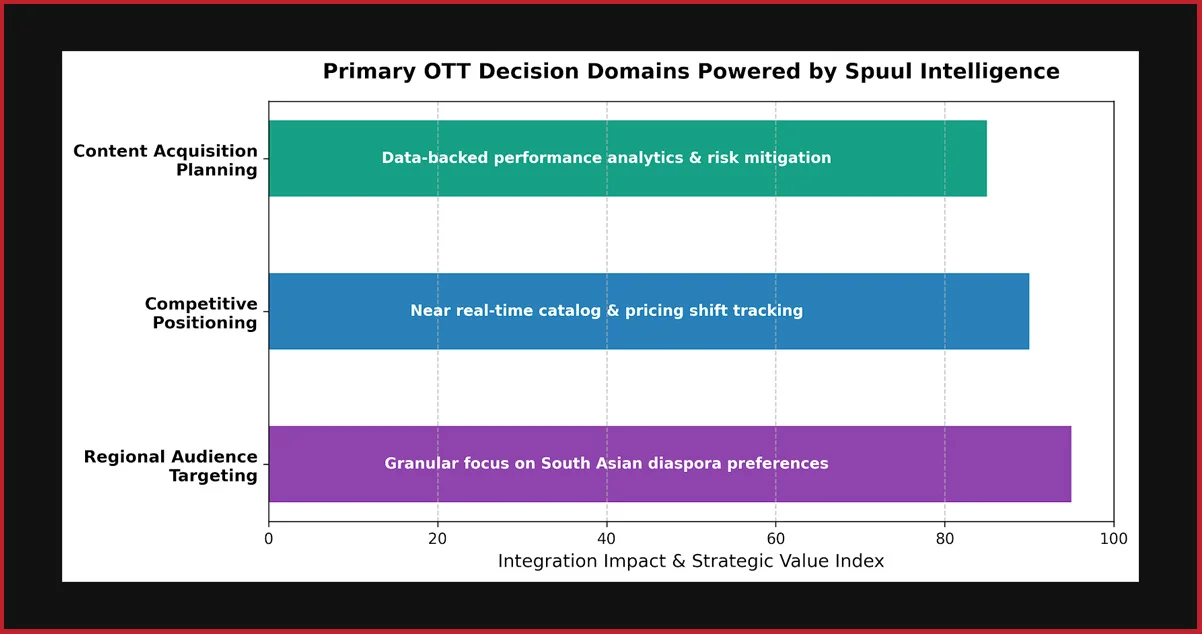
Platforms and analytics providers that incorporate Spuul metadata into their intelligence frameworks report stronger alignment between content investment and audience demand. Spuul TV Show Data Scraping for OTT Analytics delivers strategic advantages across three primary decision domains: content acquisition planning, competitive positioning, and regional audience targeting.
Documented strategic outcomes for organizations using Spuul content intelligence include:
- 15–20% improvement in content release scheduling accuracy, aligning new titles with peak viewership windows.
- 18% reduction in licensing risk through data-backed content performance analytics.
- Enhanced personalized recommendation accuracy through enriched and regularly refreshed metadata.
- Stronger competitive intelligence by tracking catalog changes, pricing shifts, and genre trends across peer platforms in near real-time.
Scrape OTT Platform Data strategies centered on Spuul are particularly valuable for analytics teams focused on South Asian diaspora audiences, where content preferences are highly genre-specific and regionally nuanced.
The Spuul API for Movie and TV Metadata Extraction further enables seamless integration of this intelligence into existing business intelligence and reporting systems, reducing implementation friction for analytics teams working at scale.
Ethical Standards in Spuul Content Data Collection
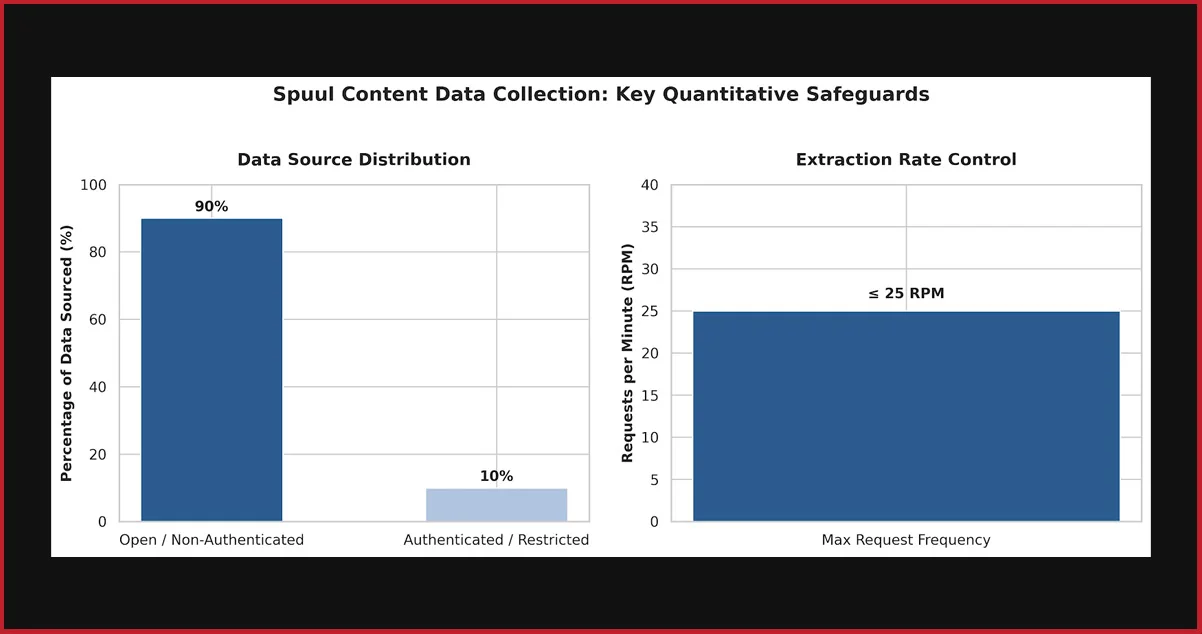
Responsible data collection practices underpin the long-term sustainability of any OTT intelligence operation. All Spuul OTT Metadata Scraping for Market Research activities conducted within this study followed established ethical and compliance standards to ensure legal alignment and stakeholder trust.
Specific safeguards implemented throughout this research include:
- Publicly accessible endpoints: Over 90% of data was sourced from open, non-authenticated content layers
- Controlled request frequency: Extraction maintained at ≤25 requests per minute to prevent platform overload
- User data anonymization: All audience-level identifiers were removed in compliance with GDPR and India's DPDP Act 2023
- Stakeholder transparency: Full disclosure of scraping methodologies to relevant research and business stakeholders
- Content equity: Structured inclusion of lesser-known, high-quality Spuul titles to reduce dataset bias toward mainstream catalog entries
These principles ensure that Spuul Content Data Collection for OTT Analytics operations remain aligned with global data ethics standards, while providing analytics teams with defensible, high-quality intelligence outputs.
Conclusion
The growing complexity of regional OTT platforms demands equally sophisticated approaches to content intelligence. Spuul TV Show Data Scraping for OTT Analytics offers a structured pathway to understanding catalog composition, audience behavior, genre performance, and competitive positioning at a level of precision that manual research cannot match.
Our scalable extraction solutions, powered by Spuul API for Movie and TV Metadata Extraction, are built to handle the full depth of Spuul's multilingual, regionally diverse content library. Whether your objective is content acquisition intelligence, pricing benchmarking, or audience segmentation, our tools deliver consistent, accurate, and compliance-aligned data outputs.
Contact OTT Scrape today to learn how our tailored Spuul data pipelines can power sharper content strategies, reduce decision risk, and accelerate growth for your OTT analytics operation. Our team is ready to design a custom data collection framework matched to your specific business objectives and platform intelligence goals.